About ScribeCrate
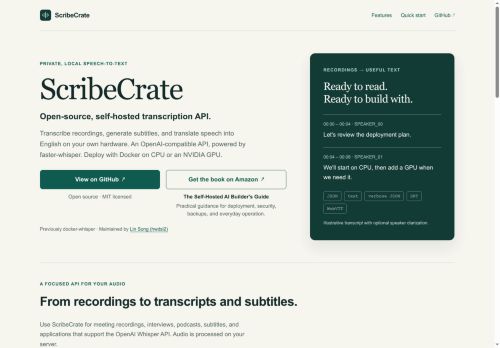
ScribeCrate is an open-source, self-hosted transcription API that performs speech-to-text, subtitle generation, and English translation on local hardware. It exposes OpenAI-compatible endpoints for transcription and translation, enabling integration with Whisper-compatible clients.
Processing occurs locally with an offline mode option and persistent model caching to reduce repeated downloads. Deployment uses Docker and supports CPU or NVIDIA GPU acceleration. Optional speaker diarization marks speakers per segment, and decoded segments can be streamed over server-sent events.
Outputs include plain text, structured JSON, and subtitle formats, and the project runs faster-whisper with Whisper models under an MIT license.
Key Features
Use Cases
Who is it for?
Processing occurs locally with an offline mode option and persistent model caching to reduce repeated downloads. Deployment uses Docker and supports CPU or NVIDIA GPU acceleration. Optional speaker diarization marks speakers per segment, and decoded segments can be streamed over server-sent events.
Outputs include plain text, structured JSON, and subtitle formats, and the project runs faster-whisper with Whisper models under an MIT license.
Key Features
- Open-source, self-hosted transcription API performing speech-to-text, subtitle generation, and English translation on local hardware
- OpenAI-compatible endpoints for transcription and translation enabling Whisper-compatible client integration
- Local/offline processing with persistent model caching to avoid repeated downloads
- Docker-based deployment with support for CPU and NVIDIA GPU acceleration
- Optional speaker diarization per segment and streaming of decoded segments via server-sent events (SSE)
Use Cases
- Create time-aligned subtitles and local English translations for training and marketing videos using ScribeCrate's self-hosted Docker deployment, hardware-accelerated transcription and persistent model caching to ensure fast, private processing with SSE-streamed transcript segments
- Build a secure meeting transcription and indexing pipeline that leverages offline speech-to-text, optional speaker diarization and OpenAI-compatible endpoints to produce searchable, speaker-attributed notes without sending audio to third parties
- Offer a podcast and media workflow to generate editable transcripts, batch subtitle files and translated captions locally using the subtitle generation API and GPU/CPU acceleration to cut turnaround time while keeping content on-premise
Who is it for?
- Software developers integrating speech-to-text and subtitle features
- Devops and system administrators deploying self-hosted services with docker
- Privacy-conscious organizations requiring on-premise transcription
- Media producers, podcasters, and video editors needing captions and transcripts
- Accessibility and captioning teams creating subtitles for content
- Researchers and data scientists working with speech datasets
- Localization and translation teams needing english translation and subtitle exports
- Journalists and legal professionals requiring confidential, offline transcription
- Startups and small businesses seeking low-cost, self-hosted asr
- Open-source enthusiasts and hobbyists experimenting with whisper models
No review yet!
More Transcriber AI Tools
Explore other transcriber tools with user ratings, pricing details, and in-depth descriptions. Updated regularly by our editorial team.