About SGLang
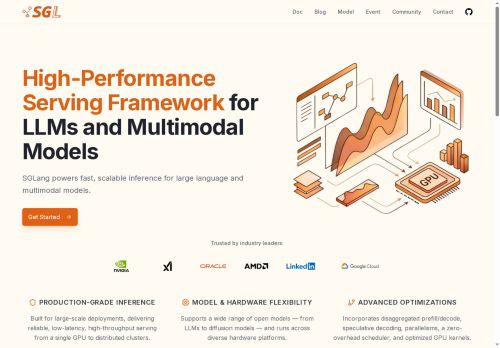
SGLang is a high-performance serving framework for large language and multimodal models. It provides scalable, low-latency inference with high throughput across deployments from a single GPU to distributed clusters.
The engine supports a wide range of open models and diverse hardware platforms, enabling unified model and hardware flexibility.
Runtime optimizations include disaggregated prefill/decode, speculative decoding, parallelism strategies, a zero‑overhead scheduler, and optimized GPU kernels to reduce latency and increase throughput. Deployment is available via pip or Docker and exposes OpenAI-compatible API endpoints for integration.
The project includes tooling for multi-node scaling, monitoring, and community-driven extensions via GitHub and discussion channels.
Key Features
Use Cases
Who is it for?
The engine supports a wide range of open models and diverse hardware platforms, enabling unified model and hardware flexibility.
Runtime optimizations include disaggregated prefill/decode, speculative decoding, parallelism strategies, a zero‑overhead scheduler, and optimized GPU kernels to reduce latency and increase throughput. Deployment is available via pip or Docker and exposes OpenAI-compatible API endpoints for integration.
The project includes tooling for multi-node scaling, monitoring, and community-driven extensions via GitHub and discussion channels.
Key Features
- Serving framework for large language and multimodal models
- Scalable inference from a single GPU to distributed clusters
- Unified support for a wide range of open models and diverse hardware platforms
- Runtime optimizations: disaggregated prefill/decode, speculative decoding, parallelism strategies, zero-overhead scheduler, and optimized GPU kernels
- Deployable via pip or Docker with OpenAI-compatible API endpoints and multi-node scaling/monitoring tooling
Use Cases
- Deploy a production-grade, low-latency conversational AI or customer support assistant using SGLang's OpenAI-compatible API endpoints and runtime optimizations—run on a single GPU or scale to multi-node clusters via pip or Docker for real-time responses and high throughput
- Serve multimodal applications like visual search, image captioning, or document understanding by leveraging SGLang's multimodal model serving and distributed GPU serving to process image+text inference at scale with minimal latency
- Build cost-effective batch and streaming inference pipelines for personalization, recommendation, or analytics by deploying SGLang across multi-node clusters, using speculative decoding and other optimizations to maximize throughput and reduce inference latency while keeping integration simple
Who is it for?
- Machine learning engineers
- Mlops engineers
- Infrastructure/platform engineers
- Devops engineers
- Ai/ml researchers
- Data scientists deploying production models
- Startups building llm- or multimodal-powered apps
- Enterprise engineering teams
- Cloud service providers and sres
- Gpu/cluster administrators
- Software engineers integrating models via openai-compatible apis
- Open-source contributors and community developers
No review yet!
More Infrastructure tools AI Tools
Explore other infrastructure tools tools with user ratings, pricing details, and in-depth descriptions. Updated regularly by our editorial team.