About Magnitude
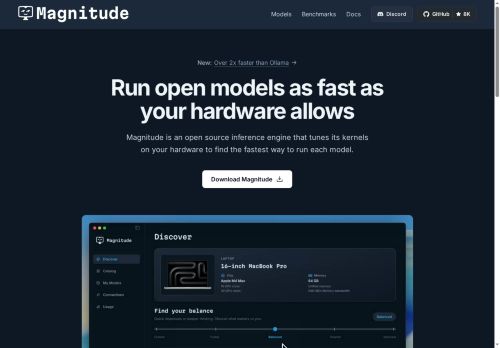
Magnitude is an open source inference engine that tunes model kernels to the host hardware to optimize local model execution.
It performs per-model kernel tuning during download to identify the fastest execution configuration without altering model outputs.
Speculative decoding and an integrated drafter reduce inference latency, while quantized key-value storage lowers memory use and frees resources when sessions end.
Concurrent sessions share prefix caches to prevent slowdown and improve throughput for multi-session workloads.
One-click integrations connect common agents and OpenAI-compatible APIs for straightforward workflow integration.
The desktop app supports macOS, Linux, and Windows and runs on Apple Silicon, NVIDIA, AMD GPUs, or CPU-only systems.
Benchmarks report faster prefill and decode times versus other local engines across popular open-weight models, and the project is distributed under the Apache 2.0 license with models and data kept on-device.
Key Features
Use Cases
Who is it for?
It performs per-model kernel tuning during download to identify the fastest execution configuration without altering model outputs.
Speculative decoding and an integrated drafter reduce inference latency, while quantized key-value storage lowers memory use and frees resources when sessions end.
Concurrent sessions share prefix caches to prevent slowdown and improve throughput for multi-session workloads.
One-click integrations connect common agents and OpenAI-compatible APIs for straightforward workflow integration.
The desktop app supports macOS, Linux, and Windows and runs on Apple Silicon, NVIDIA, AMD GPUs, or CPU-only systems.
Benchmarks report faster prefill and decode times versus other local engines across popular open-weight models, and the project is distributed under the Apache 2.0 license with models and data kept on-device.
Key Features
- Per-model kernel tuning during download to identify the fastest execution configuration without altering model outputs
- Speculative decoding and integrated drafter
- Quantized key-value storage with resource release on session end
- Concurrent sessions share prefix caches
- Cross-platform desktop app (macOS, Linux, Windows) with support for Apple Silicon, NVIDIA, AMD GPUs, and CPU-only systems
Use Cases
- Build low-latency, privacy-preserving local chatbots on laptops and edge servers using Magnitude's per-model kernel tuning, speculative decoding, and quantized KV storage to cut prefill/decode latency and memory usage so conversations feel instant without cloud dependency
- Accelerate multi-agent and agent-workflow systems by leveraging Magnitude's speculative decoding engine, multi-session prefix cache, and cross-platform CPU/GPU support to share context across sessions, reduce response time, and run parallel agents efficiently
- Deploy real-time code-completion and drafting assistants in resource-constrained environments by using hardware-optimized inference, quantized key-value storage, and kernel tuning to minimize footprint while maintaining high throughput for fast completions and seamless integration into developer tools
Who is it for?
- Machine learning engineers
- Ai researchers
- Application developers integrating local llms
- Mlops and system integrators
- Privacy-conscious developers and users
- Data scientists benchmarking models
- Startups and product teams building on-device ai
- Desktop power users and hobbyists running models locally
- Developers targeting apple silicon, nvidia, amd, or cpu-only systems
- Enterprises needing on-device inference and compliance-focused deployments
- Developers building multi-session or high-throughput ai services
- Developers integrating agents or openai-compatible apis
No review yet!
More Infrastructure tools AI Tools
Explore other infrastructure tools tools with user ratings, pricing details, and in-depth descriptions. Updated regularly by our editorial team.