About Colibri
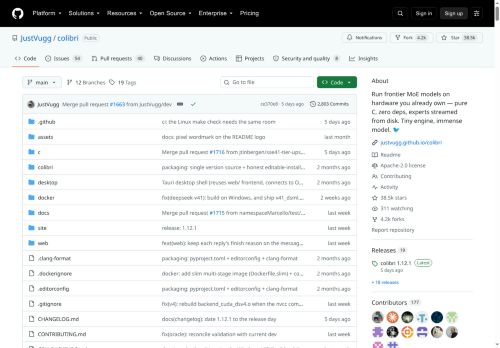
Colibrì is an open-source inference engine that streams Mixture-of-Experts (MoE) model weights from disk into a unified VRAM/RAM/storage hierarchy to reduce fast-memory requirements.
It implements per-layer expert prefetching, a measured LRU plus learned pinning cache, and batched expert unions to overlap I/O and compute. The runtime is a single C binary with zero runtime dependencies and multiple backends (CPU, CUDA, Metal, Vulkan) for heterogeneous execution.
Features include compressed persistent KV state, token-exact forward validation, optional speculative drafting, and a planner for RAM/VRAM placement and multi-SSD staging.
Supported model families include GLM Flash, Inkling, Kimi K3, DeepSeek V4/V4.1, Qwen variants, and OLMoE, with per-model engine binaries. Bundled tools provide a CLI (coli), a web dashboard with live token and expert metrics, conversion utilities, and benchmark/tuning workflows.
The project focuses on measurable end-to-end experiments for placement, routing, compression, and heterogeneous scheduling.
Key Features
Use Cases
Who is it for?
It implements per-layer expert prefetching, a measured LRU plus learned pinning cache, and batched expert unions to overlap I/O and compute. The runtime is a single C binary with zero runtime dependencies and multiple backends (CPU, CUDA, Metal, Vulkan) for heterogeneous execution.
Features include compressed persistent KV state, token-exact forward validation, optional speculative drafting, and a planner for RAM/VRAM placement and multi-SSD staging.
Supported model families include GLM Flash, Inkling, Kimi K3, DeepSeek V4/V4.1, Qwen variants, and OLMoE, with per-model engine binaries. Bundled tools provide a CLI (coli), a web dashboard with live token and expert metrics, conversion utilities, and benchmark/tuning workflows.
The project focuses on measurable end-to-end experiments for placement, routing, compression, and heterogeneous scheduling.
Key Features
- Streaming Mixture-of-Experts (MoE) model weights from disk into a unified VRAM/RAM/storage hierarchy
- Per-layer expert prefetching with a measured LRU plus learned pinning cache
- Batched expert unions to overlap I/O and compute
- Single C runtime binary with zero runtime dependencies and multiple backends (CPU, CUDA, Metal, Vulkan) for heterogeneous execution
- Planner for RAM/VRAM placement and multi-SSD staging
Use Cases
- Run large Mixture-of-Experts (MoE) language models on commodity servers using Colibrì's MoE streaming, per-layer expert prefetching and unified VRAM/RAM/storage hierarchy to minimize GPU VRAM usage, leverage multi-SSD model staging and learned caching to host models that otherwise wouldn't fit and cut inference costs without changing model architecture
- Deploy low-latency, reproducible conversational agents and chatbots using Colibrì's token-exact forward validation and batched expert unions, combining heterogeneous multi-backend execution (CPUs/GPUs) and placement planning to ensure consistent outputs, scale throughput, and meet real-time SLAs
- Build scalable recommendation and personalization inference pipelines using Colibrì's learned caching and compressed KV persistence to keep hot expert state in fast memory while staging cold experts on SSDs, using placement planning and multi-backend execution to maximize throughput across mixed-hardware clusters
Who is it for?
- Ml inference engineers
- Ml infrastructure / mlops engineers
- Systems researchers and engineers working on model serving
- Performance and benchmarking engineers
- Research scientists experimenting with moe models
- Gpu and heterogeneous-compute engineers (cuda/metal/vulkan)
- Model deployers at startups and enterprises
- Data center and cluster operators
- Devops / sre responsible for production llm services
- Tooling and observability engineers for model monitoring
No review yet!
More Infrastructure tools AI Tools
Explore other infrastructure tools tools with user ratings, pricing details, and in-depth descriptions. Updated regularly by our editorial team.